Schlep as a Service
AI has us questioning the moats of Software as a Service. Each company seems to be caught between the pincers of “The labs will build it” or “I’ll just build it myself”. There are many instances where those pincers have already closed. Data analytics frontends like Tableau are one such example1. Today, if the software is sufficiently low stakes, and not too complex it can be few-shotted by coding agents, or at least in a few weeks by a couple of engineers + AI.
As the models get better, the software moats of high fixed costs, ongoing maintenance, and painful migration, are clearly shrinking. The Valley-brained take is that these moats will evaporate completely. The labs themselves, and even Nvidia2 are not safe, as is anyone who produces something intangible. This tweet captures the argument in the limit:
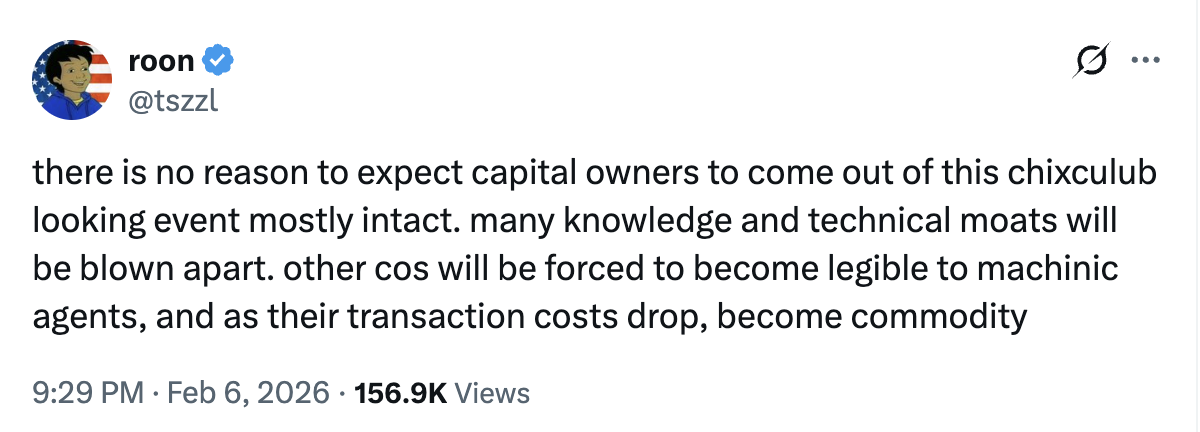
There are various counter arguments to the SaaS-pocalypse. I believe the strongest counter argument: schlep, is underpriced. To explain why, I’ll start by applying Paul Graham’s classic Schlep Blindness concept to the age of AI. Then, we’ll expand the notion of schlep to real world feedback loops, that still maintain software moats post-AGI.
Real World Integration
The real world requires agreements to set up commercial integrations. The accounting software Xero has custom integrations with every bank in Australia and New Zealand, not to mention each country’s respective tax authorities. No matter how quickly a startup can build a better product, agents do very little to speed up the process of signing off on a proprietary bank integration.
A second important moat in this category is real world supply. Early Expedia account managers have legendary stories of trudging out to remote locations like the Scottish highlands, just to convince hoteliers to list on a site they’d never heard of, on an internet they’d never used. This early work compounded and gave Expedia and Booking the moats they have today.
A startup with no distribution, will have a hard time encouraging hoteliers to schlep their way through another commercial agreement. Nonetheless, Expedia’s actions imply they are responding to that threat. For the last 2 years, Expedia’s B2B revenue grew at ~20% while their B2C revenue only grew at 2%3. That shows at least some willingness to sacrifice UI revenue for API revenue.
Whether that was intentional or not, the figures are bullish for Expedia’s moat retention. Future distribution might occur via startups that integrate with consumer agents. Expedia has the supply + API, startups can approach them and use it. In the AI transition, Expedia still gets paid for the supplier relationships they maintain.
I expect these moats to persist in the medium term, whether incumbents accept the change and lean into them is of course case dependent (and worth challenging). The point is that real-world software moats are currently alive and well. In the next section, we examine a wider class of deeper real world moats that apply to software.
Software is Empirical
In machines of loving grace, Dario is optimistic about the progress that could be made in biology due to AI. However, he notes we are fundamentally rate limited by running experiments. Biology deals in living cells and organisms, there is a limit to what humans/AI can know deductively. We must run (and wait for) experiments to test our theories and make progress. Everyone accepts that applies to biology, but it’s underappreciated how much that applies to writing software too.
Slack is an example of software that has an empirical moat. Slack is interesting because for a single company, it’s not that hard to replace from an engineering perspective. Slack is often discussed as “one-shotable soon”. The argument goes: Models aren’t quite there yet, but they are currently being trained to produce entire SaaS products. Soon enough, we’ll have models that can produce Slack and maintain it with very little human involvement. Then, companies will not pay for Slack, they’ll just write it themselves.
This story overlooks all the things that are hard when it comes to building something like Slack. Yes, the writing of the code got much easier, but the feedback loops did not get faster. The first version of Slack was certainly trash. Countless releases with user conversations, metrics, error logs and eventually AB tests were all critical in getting Slack to where it is today. All of these move at human speed, just like our biological experiments.
If you’ve ever worked on a software product4 from scratch, you’ve felt the point I’m making. Iteration after iteration, you’re slowly making things less and less shit, the real world feedback is essential. Even if agents were exceptional at product management, product management is fundamentally bottlenecked by human interaction with the software, which runs at a speed we do not control5.
This is doubly true for engineering decisions at scale. In complex systems, over the course of a decade, thousands of issues are observed and fixed, complex trade-offs are made, all downstream of real world data. A lot of these issues are only observed at scale, which means it also takes considerable resources to make the observation that the software is not correct.
A super intelligent AI will make better product and engineering choices. It will run simulations and execute the optimization loop in fewer releases, but simulations are fundamentally limited by chaos. It’s a superintelligence, not an omniscient god. It’s constrained by what it can observe + randomness. Thinking that Slack and the way it is run can just be copied, is to overlook the 1000’s of trade-offs and system design decisions that could only have been made after observing millions of customers use the system over many years.
Both humans or agents are complex, chaotic systems (just like cells). You are optimizing the software for those chaotic beings. The more complex your problem, the more you benefit from optimizing across a large pool of humans/agents. So when companies or the labs are faced with implementing slack versus buying, it’s an easy choice, use what already works.
A great pre-LLM example of buy-it-or-build-it is the hyperscalers and their internal tooling. Initially they built their own tools out of necessity6, but as time went on the SaaS ecosystem caught up and made much better versions of these internal tools7. If you’ve ever worked for a big tech company, you’ll know how bad those internal tools are. Here’s Navi from Neetcode literally citing internal tools as his reason for quitting Google. One key reason these SaaS companies were better is that these SaaS companies observed far more users than an internal tool ever could8.
To summarize, exposure to the distribution of economically valuable actions is a big, underrated moat. Get your software in the hands of your users early and often, and start compounding through iteration.
Footnotes
-
Coding agents produce beautiful graphs on the fly, and can schedule that reporting easily. ↩
-
Nvidia does not actually manufacture its own chips. It designs them, and sends large files to TSMC to manufacture them, which is why it is lumped in with the software companies when this argument is made. ↩
-
This is lower than the growth rate of global online travel booking value of 9% ↩
-
Or a piece of writing, a song, a prepared dj set, all complex knowledge work has this character. ↩
-
Even if the software is exclusively used by agents, the ultimate feedback for that software’s quality is the impact those agents have on humans in the real world. As long as human values reign supreme (fingers crossed) this feedback loop will be bottlenecked. ↩
-
These companies were the only ones dealing with those challenges at scale. ↩
-
This is not a universal law, there are many tools where it makes sense to build them yourself, particularly where the integration costs are expensive. Deployment pipelines are a good example of this (although I’m yet to work at a company that offers a better experience than gitlab or github CI). ↩
-
Of course, they also ran a much stronger optimization loop (make this SaaS tool excellent or die). ↩